The scene animates, but the report says the requested prompt details are not properly reflected.
What was measured
Prompt Accuracy
How faithfully the video follows the motion, scene, and detail instructions given in the prompt.
decisive for this rankingtransformation
For image-to-video, following the requested motion and scene changes is central to judging whether the tool produced the intended video. (3 of 3 judges)
What was given, what came back
Test input: 3D rendered street scene image with forward dolly prompt · image · group: image-to-cinematic-video
Input — what we sent
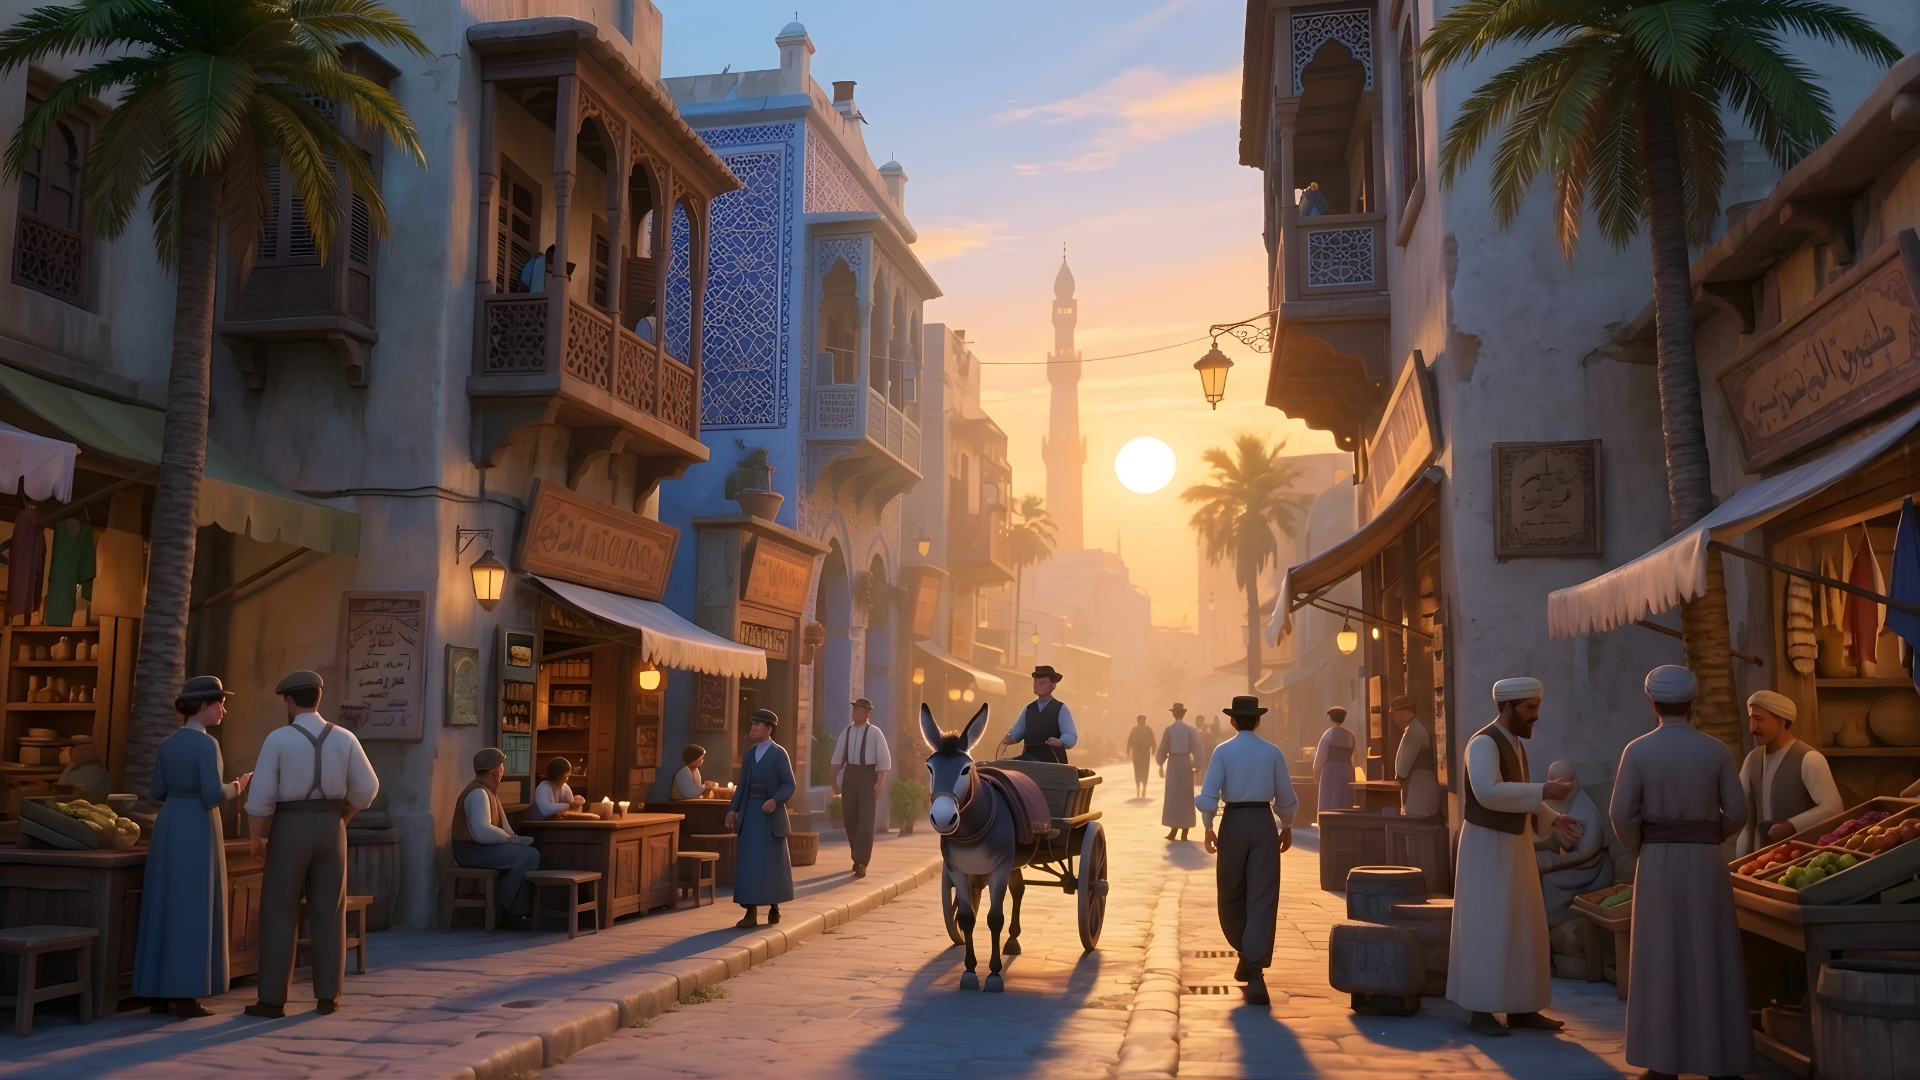
3D rendered street scene image with forward dolly prompt
A rendered 3D street scene with multiple characters and environment detail, tested using a forward-dolly cinematic prompt with crowd motion, cart movement, atmospheric haze, and sunset lighting.
Why this input is hard
- · Complex multi-subject scene animation
- · Character consistency in crowd motion
- · Camera movement stability during forward dolly
- · Environmental motion such as clouds, trees, and birds
- · Prompt adherence across foreground and background elements
Output — unretouched
Also checked on this input — same tool, 2 other criteria
Motion Quality & Realism✓ WorkedThe tool maintains smooth animation and consistent scene motion across multiple moving subjects.Visual Consistency (No Distortion)⚠ StruggledThe tool introduces noticeable facial distortion in characters, showing that it does not reliably preserve faces and human structure in 3D scenes.
Provenance
- Observation
- 293512d4-0fe0-47d3-a867-42336caaf9a4
- Evidence run
- b8778c3c-4fb1-48b2-bf35-4e08a3b82d8e
- Study
- Generate a cinematic AI video from a single image
- Research task
- 86b94urgr
- Tested at
- not recorded
- Source
- first-party
- Evidence state
- verified
- Proof shown
- input + output shown
- Cost / latency
- not captured
- Repeat run
- not captured
- Tester
- not captured
The last three rows are honest blanks, not placeholders — our capture has no field for them yet.
Query this
get_evidence({
  tool: "leonardo-ai",
  scenario: "image-to-cinematic-video"
})
MCP · mcp.aidemos.com/api/mcp
Free with attribution.
Same input, same check — 2 other tools
measured on Prompt Accuracy
Google Flow◐ MixedIt can reproduce the core movement language of a forward-dolly street prompt, especially natural walking and interactions, but the report does not verify every requested environmental detail.PixVerse AI◐ MixedThe 3D run delivers the requested camera motion and sound effects, but the report also says clarity is reduced and characters distort, so the scene instructions are only partially preserved.
Real inputs and real outputs, no retouching · every cell queryable via API & MCP · aidemos.com