Evidence · first-party tested/Best AI Tools to Scrape Web Pages Into Clean Markdown or Structured Data
It failed to wait for client-side hydration of the size picker, leaving the size-selection area empty and returning zero available sizing attributes.
What was measured
JS DOM Hydration
How well the tool waits for and captures content rendered by client-side JavaScript on dynamic pages.
decisive for this rankingtransformation
Capturing JavaScript-rendered content is a core scraping capability for modern web pages. (3 of 3 judges)
What was given, what came back
Test input: Nike Air Force 1 '07 size options extraction · mixed
Input — what we sent
Input, verbatim
https://www.nike.com/t/air-force-1-07-mens-shoes-jBrhbr/CW2288-111 — Wait for the size selection options to fully render. Extract the product name, price, and a list of all available shoe sizes.
A Nike product page with client-side JavaScript hydration used to test whether a headless scraper waits for dynamic DOM content before extracting product details and all available shoe sizes.
Output — unretouched
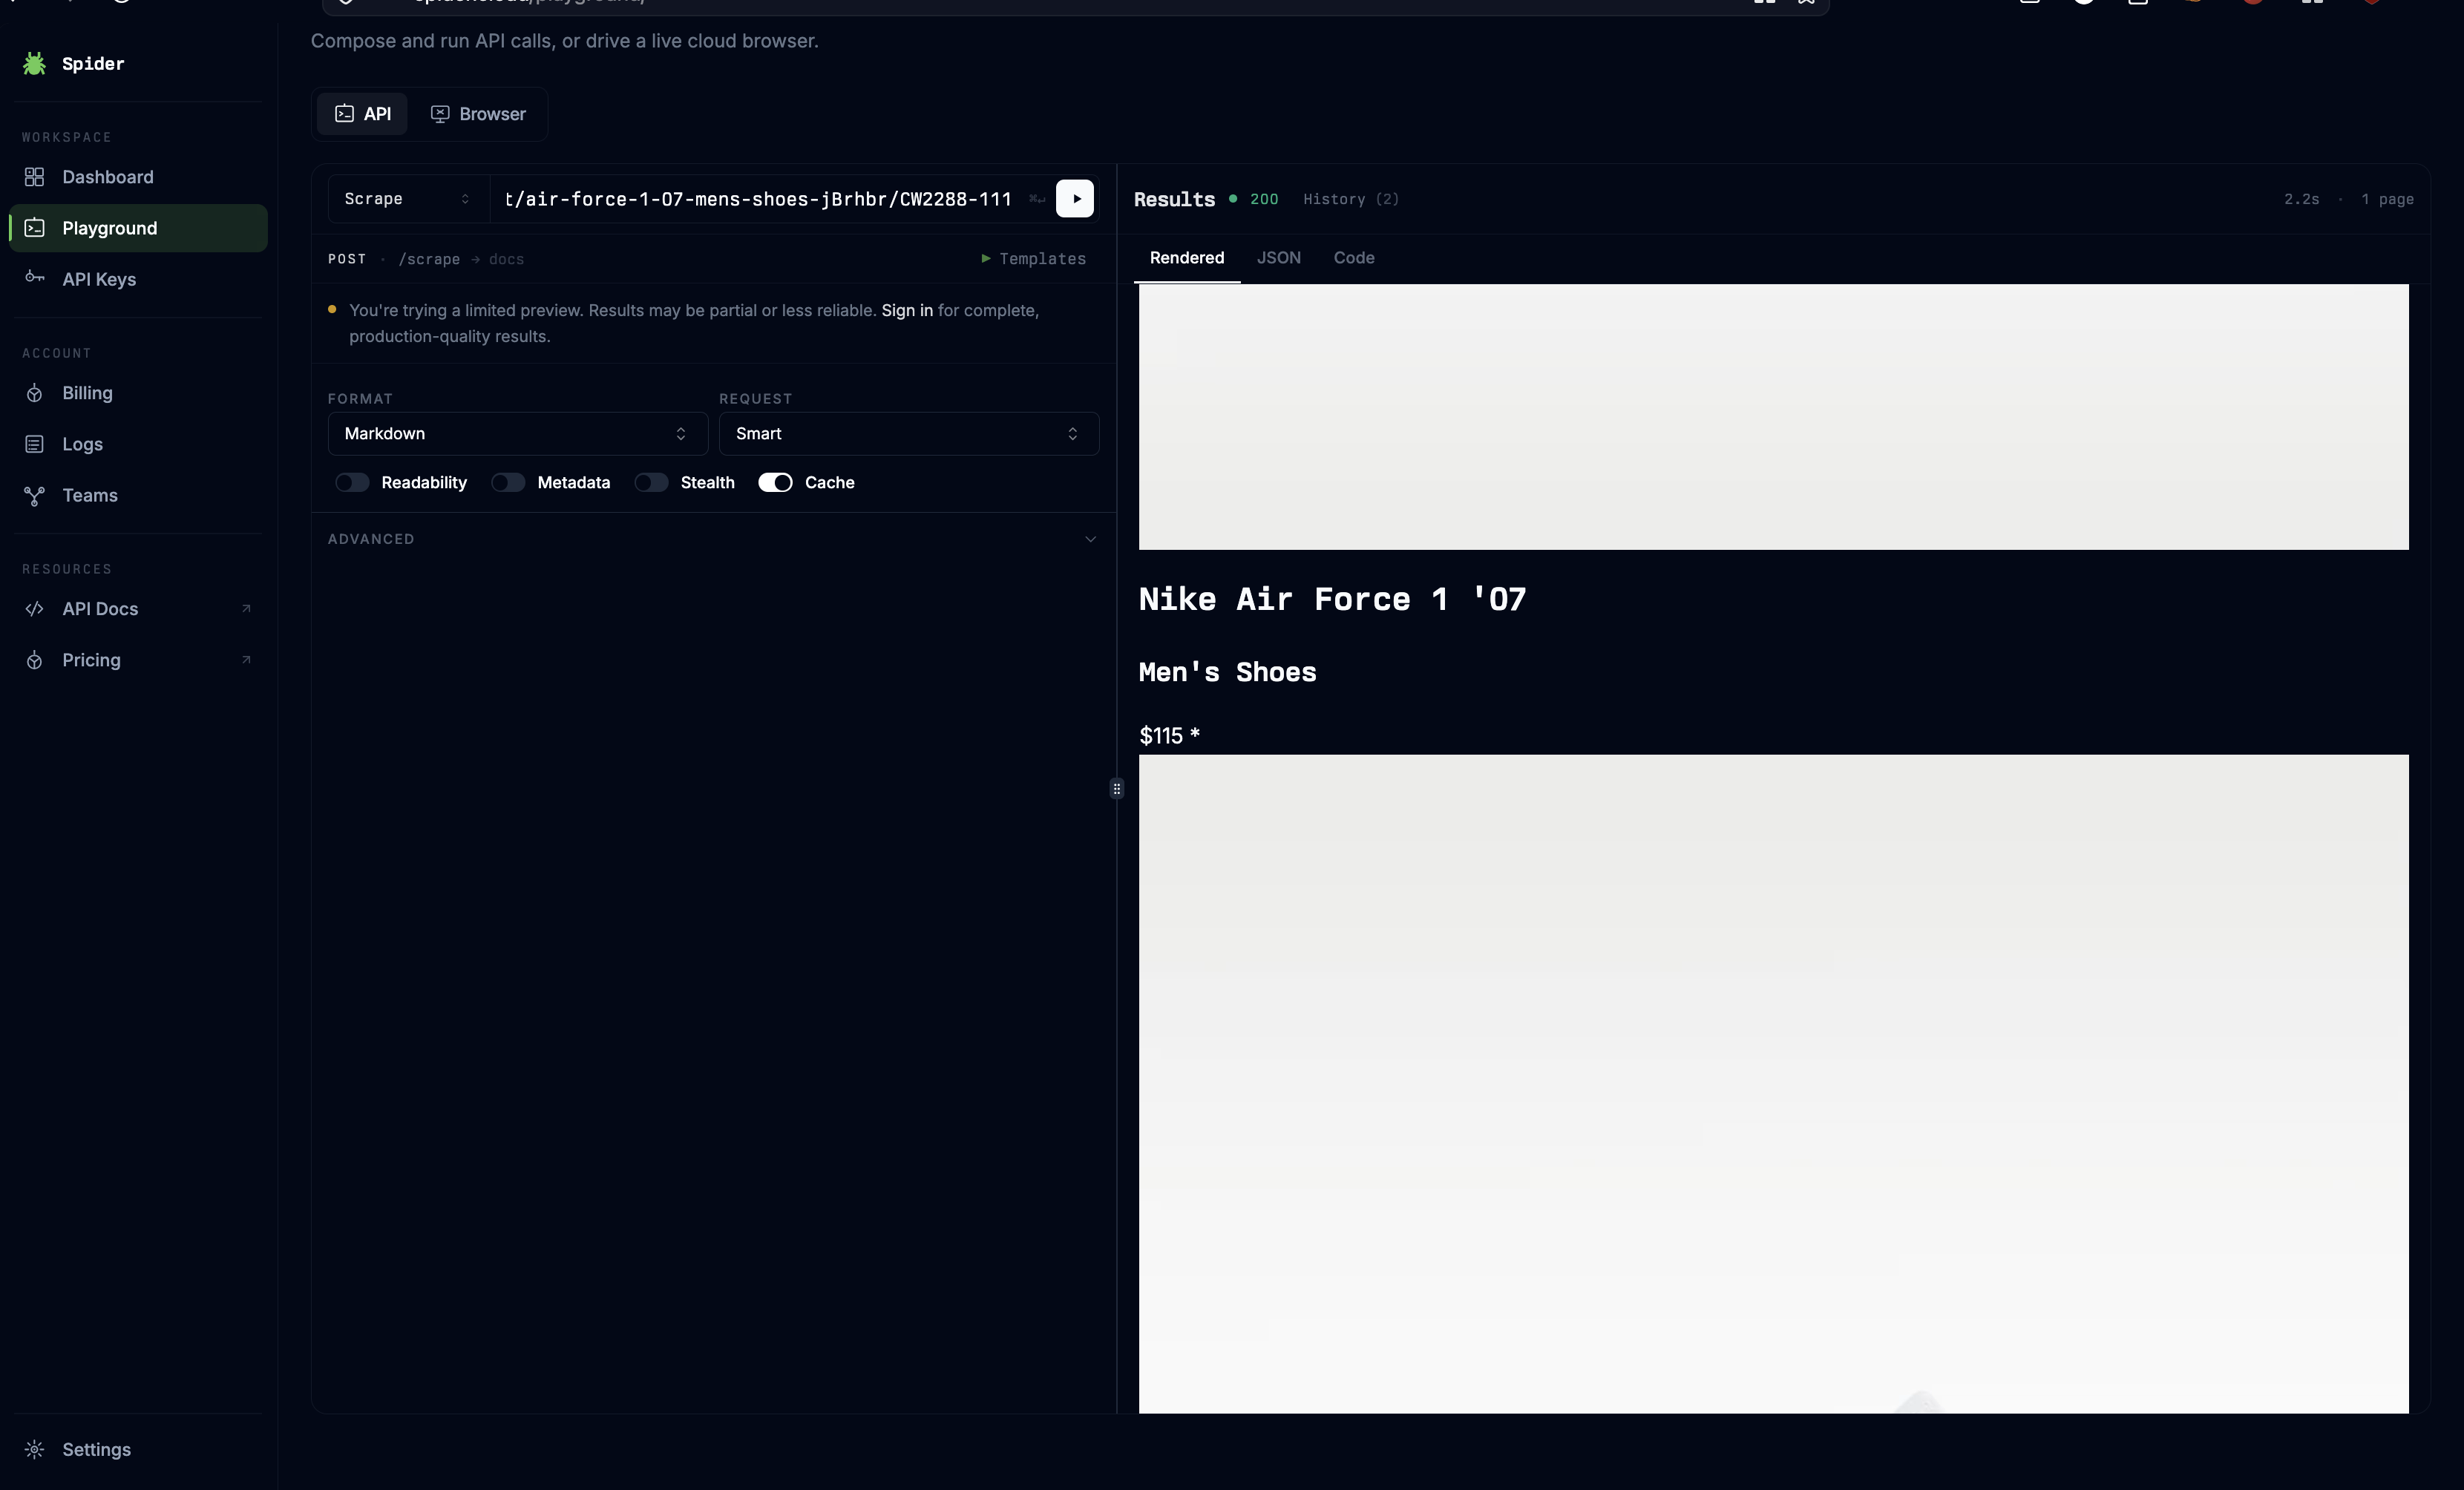
Spider Playground showing scraped Nike product results
Also checked on this input — same tool, 3 other criteria
Output Quality◐ MixedExtracted the product title, category, and price cleanly, but the result remained incomplete because the dynamic size inventory was not captured.Output Quality⚠ StruggledPreserved the product title and $115 price, but omitted the dynamic size-selection and inventory section, leaving the result incomplete.Schema Extraction Integrity◐ MixedIt can still extract static metadata cleanly, such as structural description definitions and basic marketing attributes, even when the dynamic transactional section is missing.
Provenance
- Observation
- f6d91057-4e09-49ff-9f3f-7517589be27e
- Evidence run
- 06e1dbd6-5518-4af8-aa1a-735259a75b4f
- Study
- Scrape Web Pages Into Clean Markdown or Structured Data Using AI
- Research task
- 86b9jm3a3
- Tested at
- Jun 23, 2026
- Source
- first-party
- Evidence state
- verified
- Proof shown
- input + output shown
- Cost / latency
- not captured
- Repeat run
- not captured
- Tester
- not captured
The last three rows are honest blanks, not placeholders — our capture has no field for them yet.
Query this
get_evidence({
  tool: "spider"
})
MCP · mcp.aidemos.com/api/mcp
Free with attribution.
Same input, same check — 3 other tools
measured on JS DOM Hydration
Firecrawl✓ WorkedWaits for client-side hydration and captures the complete size-selection grid, spanning M 5 / W 6.5 through M 18 / W 19.5.Jina AI Reader✗ FailedIt did not capture the client-rendered size selector; after 7.0 s the extract still lacked the live size grid and showed only static page content.Skyvern✓ WorkedWaits for the client-rendered product page to hydrate and extracts the size grid instead of stopping at the initial shell.
This evidence is published in
Real inputs and real outputs, no retouching · every cell queryable via API & MCP · aidemos.com